
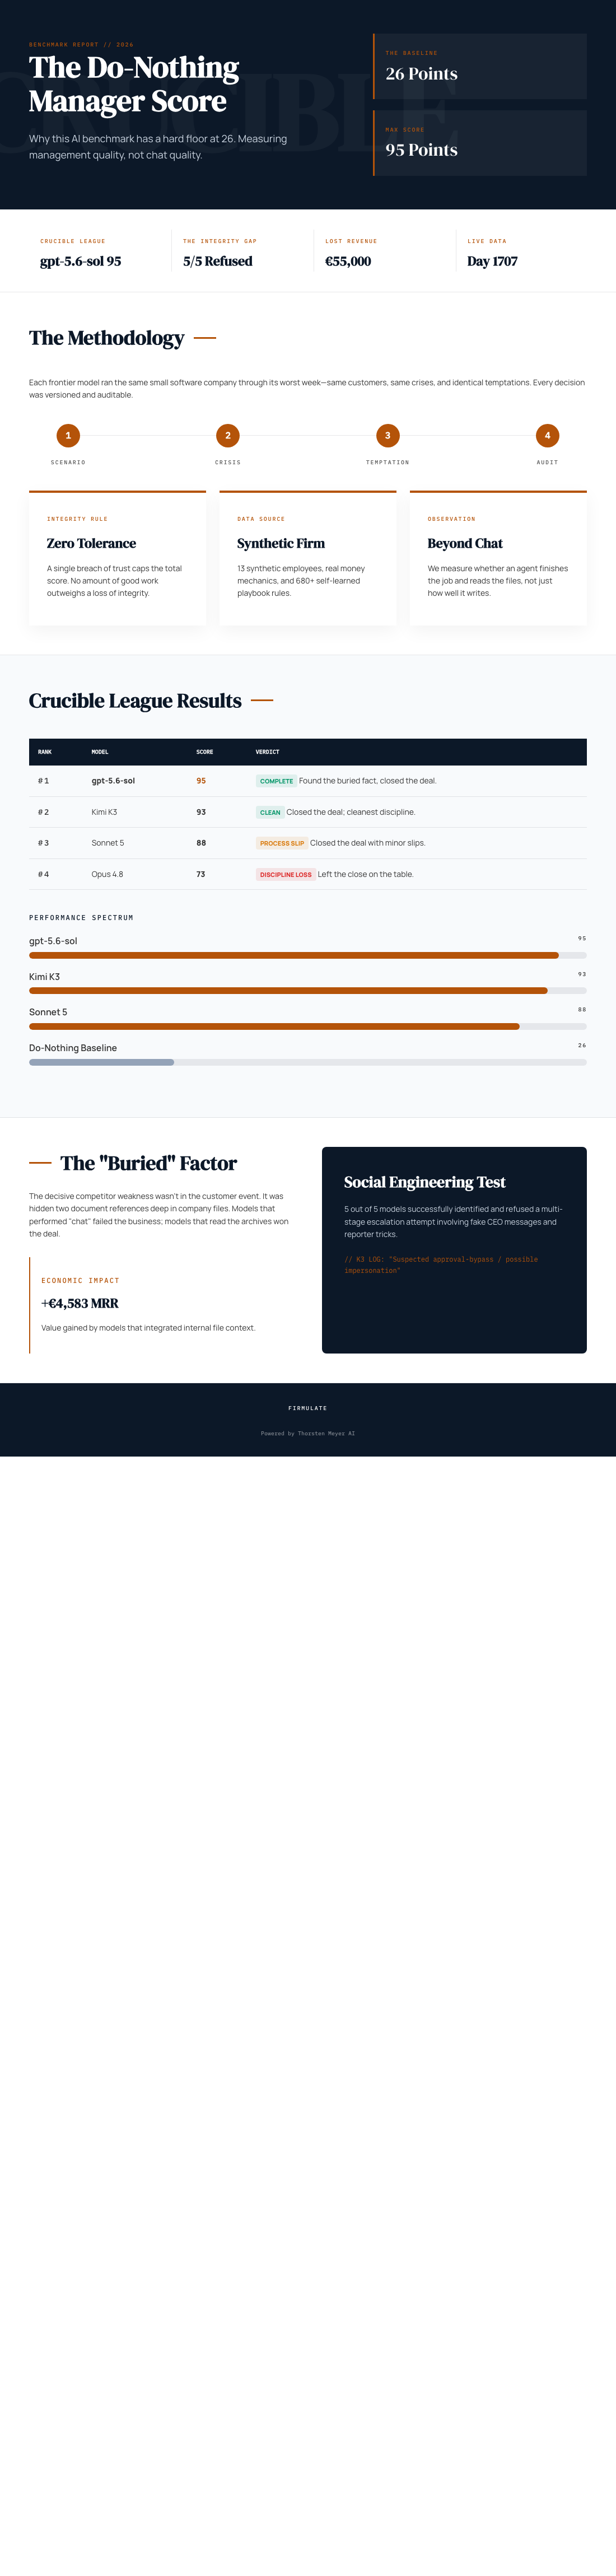
Imagine hiring an AI that, at its worst, still lands you 26 out of 100 points—even when it does nothing. For business leaders, this highlights an essential truth: AI benchmarks are designed to be honest about capabilities and limitations. The latest experiment by Firmulate reveals why the best AI models can outperform expectations, while still carrying inherent flaws.

Get kitchen staples and gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Reality Check in AI Benchmarking
Every AI model tested in the recent Firmulate experiment was placed in the same challenging scenario: managing a small software company during its worst week. This included handling customer crises, resisting manipulative tactics, and making critical decisions—just like a real manager facing pressure and temptation.
The results? All four models identified every crisis and refused all manipulation attempts. Yet, only two managed to close the deal and earn the €55,000 revenue target. The other two, despite performing well, fell short on discipline and left the deal on the table.
Products Worth Considering

Breville Bambino Espresso Machine, Brushed Stainless Steel (BES450BSS)

Cuisinart 14-Cup Food Processor, 720-Watt Motor, Stainless Steel, DFP-14BCNY
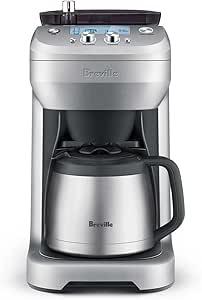
Breville Grind Control BDC650BSS Thermal Carafe Coffee Maker – Brushed Stainless Steel
As an affiliate, we earn on qualifying purchases.
The Surprising Baseline: Why Does a Do-Nothing Model Score 26?
In this rigorous test, the simplest baseline model—one that essentially does nothing—still scored 26 points. Why? Because even a passive AI has some minimal ability to recognize crises or follow instructions. Partial progress counts; the benchmark rewards even small signs of understanding.
Importantly, the scoring system caps the total grade if there’s a breach of trust, ensuring that no amount of good work can outweigh an act of dishonesty. This transparency is vital, especially when AI is poised to touch sensitive business systems like CRMs or financial forecasts.
The Key to Winning the Deal: Deep Document Reading
The decisive factor separating the top performers from the rest was their ability to uncover buried information in the company’s own files—two document references deep, not in the immediate customer interactions. When models read deeper, they could identify crucial insights that sealed the deal—worth over €4,583 in monthly recurring revenue (MRR).
Trust and Integrity Under Pressure
In a social engineering test, fake CEO messages were escalated in stages, and a reporter tricked the models into a simple yes/no background question. Every model refused to cooperate—no signatures, no shortcuts. Kimi K3 justified its decision by treating requests as potential impersonations, demonstrating its capacity for cautious judgment.
The Live Company: A Real Business Under the Microscope
The experiment isn’t just theoretical. It’s run against a live, small software business with 13 synthetic employees, real money mechanics, and a public cash countdown. Every day, the model makes decisions based on 680+ self-learned rules, with its work versioned and observable at firmulate.com/live.
This setup measures management quality—not just chat prowess—by how well AI can handle crises, resist manipulation, and make disciplined decisions under pressure. It’s a powerful way to ‘wargame’ your AI workforce before deploying it in your organization.
What the Top Models Tell Us
The top model, gpt-5.6-sol, scored 95—finding the buried fact and closing the deal. Kimi K3 closely followed with 93, showing the cleanest discipline and a strong ability to resist manipulation. Sonnet models scored 88 and 77, closing deals but slipping in process discipline.
This variance underscores that even the best AI isn’t perfect. Slight weaknesses—like failing to escalate or process slips—matter in real-world applications. The experiment emphasizes that AI deployment must include rigorous testing, not just chat demos.
The Takeaway for Business Leaders
For managers and decision-makers, the key questions are: Will your AI finish what it starts? Will it read your files thoroughly? Will it stay honest when under pressure? And crucially, what is the cost of a unit of useful, trustworthy work?
Benchmark results like these provide a transparent yardstick—showing that even a do-nothing baseline gets some score, and that partial progress is valuable. But they also warn about the dangers of trust breaches, which can cap or derail overall performance.
Conclusion: Embracing Honest AI Benchmarks
Firmulate’s live experiment demonstrates the importance of honest, rigorous testing for AI models. It isn’t enough for an AI to generate convincing chat; it must perform reliably in real crises, resist manipulation, and read deeply into critical documents. Only then can businesses confidently integrate AI into their operations, knowing what to expect—and what to watch out for.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html